
Senior Data Engineer
Bengaluru · Senior
Applicants who checked fit first are 3.1× more likely to hear back
Your score for this role already exists
ASAI compared this JD against 41 signals - skills, seniority, domain, stack overlap etc. Add a resume and it unlocks in about 30 seconds.
No credit card · 1 tap with Google
What we know about this role
MEDIUM
bureau is reviewing applications at a steady pace. Expect a standard response time as they evaluate the current pool.
First 72 hours
Early applicants get seen before the pile builds.
Not a repost
The first time we've seen this listing - it hasn't been closed and reopened.
Skills required
16 listedYou almost certainly match several of these already. Unlock your skill map to see the matches, the gaps, and what to fix first.
Job description
About Bureau
Bureau is a unified risk decisioning platform for Compliance, Fraud, and Transaction risks. Our platform is a single decision-making engine, powered by a 1 billion+ identity knowledge graph. Over 150 Banks, fintechs, retailers, and digital platforms use Bureau to verify identities faster and stop fraud earlier globally.
Bureau has raised $50M+ from renowned Silicon Valley and global investors including Sorenson Capital and PayPal Ventures and is expanding rapidly from APAC to Americas, Europe, and beyond.
Why Bureau?
Bureau is building the infrastructure that makes digital identities and transactions safe and trustworthy for billions of people. The mission is big, the problems are complex, and the impact is real.
We hire people who want that level of responsibility. People who move fast, build systems from scratch, and care deeply about turning strategy into execution. If you want predictability or narrow scope, this won't be your place. If you want to shape how a scaling global company operates—keep reading.
About the Role - Senior Data Engineer
As a Senior Data Engineer at Bureau, you will design and own the data platform that fuels our fraud detection and identity intelligence products. You'll work at serious scale, high-throughput streaming signals, a growing cloud data lake, and low-latency serving requirements where it directly impacts fraud detection.
You'll partner closely with data scientists, ML engineers, and product teams to make sure the right data is available, trustworthy, and fast, for research, reporting, model training, and real-time decisioning alike.
What You'll Do
Design and architect Bureau's cloud data lake and lakehouse, the single source of truth for identity signals, risk events, and decision outcomes across all our products
Build and operate scalable batch and streaming pipelines that ingest, clean, transform, and aggregate data from disparate sources, device SDKs, APIs, third-party data partners, and internal services
Develop and maintain orchestration workflows (Airflow) that power research, reporting, compliance analytics, and ML model training and feature pipelines
Own the reliability, observability, and cost-efficiency of production data infrastructure , with monitoring, alerting, and SLAs appropriate for a system that makes real-time risk decisions
Collaborate with data science and ML teams to design feature stores and data pipelines that shorten the path from raw signal to deployed model
Champion data engineering best practices, data quality, schema governance, testing, documentation, and mentor engineers across the team
Contribute to graph-based fraud intelligence: modeling identity networks and fraud rings using graph databases
What You'll Bring
Must have
4-8 years of hands-on big data engineering experience (batch and streaming) on the cloud, ideally AWS
Deep experience with the data lake stack: EMR, Spark, S3, Athena, and modern warehouses/lakehouses such as ClickHouse, Databricks, or Snowflake
Strong grasp of both OLAP and OLTP systems, and when to use each
Production experience with pipeline orchestration tools like Airflow or Astronomer
Familiarity with the AWS and Kubernetes ecosystem, EMR on EKS / self-hosted K8s workloads, MSK/Kafka, and RDS
Experience building RESTful APIs and architecting systems that serve both batch and real-time workloads, with solid monitoring and instrumentation practices
Strong programming skills in Python and/or Scala/Java, plus expert-level SQL
Nice to have
Graph database experience (Neo4j, TigerGraph, Amazon Neptune); we use graph technology to uncover fraud networks and hidden identity linkages
Exposure to fraud detection, risk, identity, fintech, or other high-stakes real-time data domains
Experience with data quality frameworks, data cataloging, or lakehouse table formats (Iceberg, Delta Lake, Hudi)
Experience supporting ML platforms: feature stores, training pipelines, or model-serving data flows
Our Culture
We hire self-motivated people and get out of their way
We value performance, not hours worked
Speed, ownership, and impact matter most
Compensation
Competitive salary + potential equity
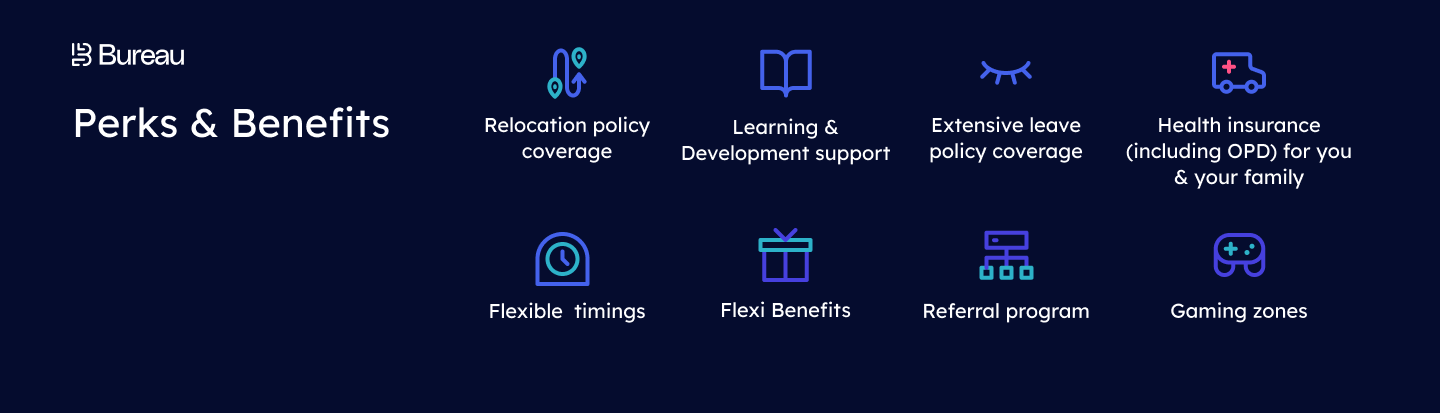
Health benefits, flexible PTO, learning budget
Free · no signup
Get tomorrow's jobs before you have to search
Daily job drops, skill trends and free resources - posted straight to the group. Leave any time.
No spam. Just jobs and resources.
Why people use ASAI
Someone shared one job with you. ASAI keeps finding the rest.
Scored, not searched. Every role ranked against your actual profile.
Alerts as often as hourly. Reach new roles while the pile is still small.
Skill gaps, spelled out. See exactly which requirements you don't meet yet.
Verified jobs, only. Say no to ghost jobs. Your time deserves respect.
More Data Engineer roles in Bengaluru
See allKeep browsing